Last Updated: October 25, 2026
Quick Summary
To prevent network downtime, address the most common causes, hardware failures, software issues, cybersecurity incidents, and human error, through proactive monitoring, redundancy systems, scheduled maintenance, and documented outage plans. Organizations with these controls in place experience 70% fewer unexpected outages than those without formal plans.
- Hardware failures, software issues, cybersecurity incidents, and human error cause roughly 25% of outages each
- Network monitoring tools catch issues in minutes instead of hours by tracking uptime, bandwidth, CPU usage, disk space, temperature, and security events
- Redundancy requires testing: measure mean time to detect under 2 minutes, failover under 60 seconds, and mean time to repair under 4 hours
- Monthly configuration backups, quarterly failover tests, and annual security audits form the core maintenance cadence
- UPS systems and generators provide backup power for routers, switches, and security appliances to prevent cascade failures
Table of Contents
- Understand the Common Causes of Network Downtime
- Implement Network Monitoring Tools to Detect Issues Early
- Set Up Network Redundancy and Failover Systems
- Create a Network Maintenance Checklist and Schedule
- Develop a Business Internet Outage Plan
- Protect Your Infrastructure with Backup Power and Data Security
- Get Started with Proactive Network Management Today
- Frequently Asked Questions
Understand the Common Causes of Network Downtime
Hardware failures are the biggest culprit.
Software issues rank second. Buggy updates crash systems. Misconfigurations lock people out of critical services.
Human error causes roughly 25% of outages. A technician unplugs the wrong cable. Someone misconfigures a firewall rule.
What most businesses miss: The real damage isn’t downtime itself, it’s the cascade.
Network downtime stems from several preventable causes, each requiring different mitigation strategies.
| Cause | Percentage or Rank | Prevention Strategy |
|---|---|---|
| Hardware failures | Biggest culprit | Proper maintenance catches wear early |
| Software issues | Second rank | Test updates and patches before deployment |
| Cybersecurity incidents | Rivals hardware failures | Monitor for ransomware, DDoS, compromised credentials |
| Human error | Roughly 25% of outages | Change control and verification procedures |
| Environmental factors | Significant | Power backup, cooling, water damage prevention |
Implement Network Monitoring Tools to Detect Issues Early
Network monitoring tools watch your infrastructure 24/7 and alert you the moment something goes wrong.
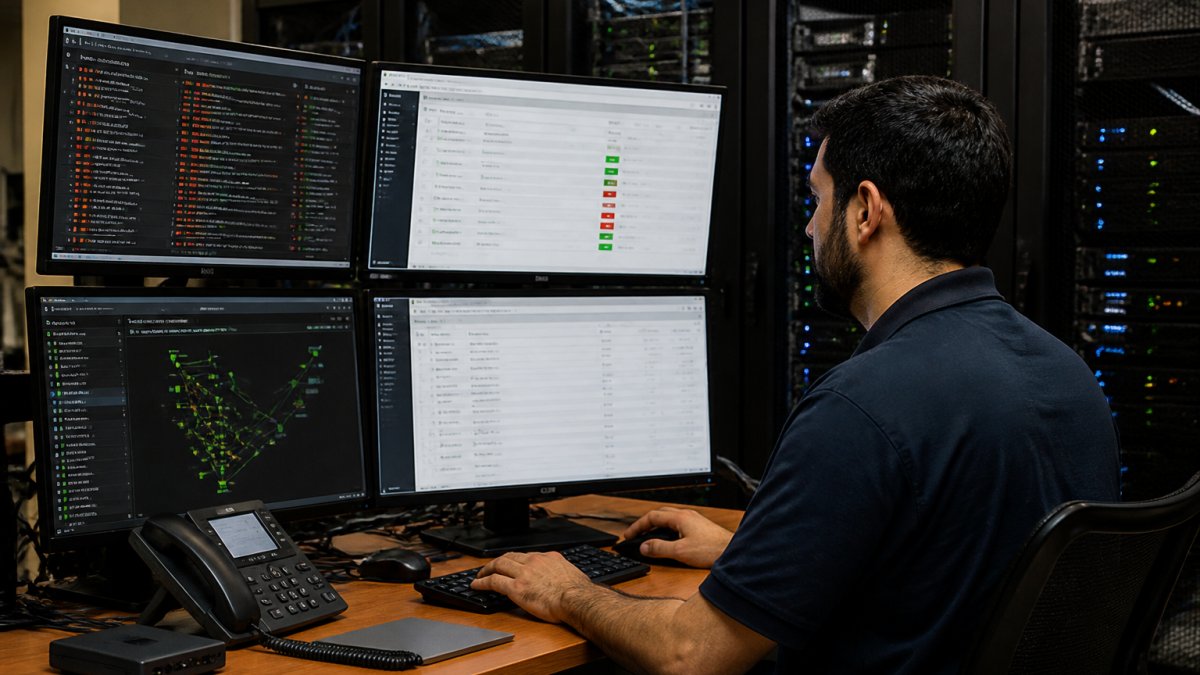
Effective monitoring tracks these critical metrics:
- Uptime and availability, Is each device online and responding?
- Network traffic and bandwidth, Are connections saturated or performing normally?
- CPU and memory usage, Are servers running hot or stable?
- Disk space, Is storage filling up and approaching capacity?
Automated alerts are non-negotiable. When a threshold is crossed, your team gets notified immediately, not after a customer complains.
Teams that check things “when we have time” fail: continuous monitoring surfaces problems automatically, giving your team time to fix them before users are affected.
Organizations using proactive network monitoring can reduce unplanned downtime by catching issues hours before they’d normally surface.
Set Up Network Redundancy and Failover Systems
A single point of failure will eventually fail. Redundancy means backup systems take over when the primary path degrades, but it only counts if you have measured it. An untested failover path is a hope, not a control.
Key redundancy components:
- Dual internet connections, Two separate ISP connections, ideally from different providers and entering the building on different physical paths
- Redundant routers and switches, Paired devices with a shared virtual gateway address so endpoints have one default gateway to trust
- Automatic failover, Routing or SD-WAN logic that shifts traffic without human intervention
- Backup power, UPS systems and generators sized to carry the load through the longest expected outage
Measure failover, don’t assume it
Failover timing is the number that matters: if failover takes 30 minutes, you had 30 minutes of downtime. Automatic failover typically completes in seconds to low minutes, but only if health checks, route preferences, and NAT rules are configured correctly. Track three numbers for every redundant path:
- Mean time to detect (MTTD), how long before monitoring flags the primary path as down
- Failover duration, time from detection to traffic flowing on the secondary path
- Mean time to repair (MTTR), time to restore the primary path and return to steady state
A practical target for many small and mid-market networks is MTTD under 2 minutes, failover under 60 seconds for internet paths, and MTTR under 4 hours for common hardware failures. Set targets that match your recovery time objective (RTO) and write them down.
Test failover safely
Testing is where most organizations stop short. A failover system that has never been exercised may not work when you need it. Use a staged approach:
- Tabletop first. Walk the team through the failover sequence on paper. Confirm who declares an incident, who verifies the secondary path, and who communicates to users.
- Component test in a maintenance window. Disable one WAN link at the router or unplug the primary uplink during a low-traffic window. Confirm traffic shifts, measure the gap, and verify voice and VPN sessions recover.
- Full-path test. Fail the primary ISP at the demarcation point (with the provider’s cooperation) and confirm the secondary path carries production traffic. Watch for asymmetric routing, stale NAT sessions, and DNS that still points at the failed path.
- Power test. Transfer the UPS to battery and confirm runtime, then test the generator transfer switch under load. Record actual runtime versus rated runtime.
- Recovery test. Restore the primary path and confirm traffic returns cleanly without flapping.
Never test failover for the first time during a real outage. Schedule tests quarterly for internet and power paths, and annually for full disaster recovery. Log every test with date, scope, observed failover time, and issues found.
Avoid the common redundancy traps
- Same-provider redundancy, Two circuits from the same ISP often share upstream infrastructure. Use different providers where possible.
- Shared physical path, Two fibers in the same conduit fail together. Confirm diverse entry points.
- Split-brain routing, Both routers advertising the same routes can cause intermittent drops. Use clear primary/secondary preferences and verify with traceroutes after each change.
- Undersized UPS, A UPS that carries the network but not the servers buys minutes, not continuity. Size backup power to the load you actually need to keep running.
Many organizations skip redundancy because it feels expensive upfront, but one major outage, lost productivity, emergency repairs, customer compensation, typically costs more than a year of redundant systems. Redundancy is insurance that pays for itself, but only when tested and measured.
Create a Network Maintenance Checklist and Schedule
Preventive maintenance stops most problems before they start, but the highest-value maintenance is controlling change. Human error and faulty deployments cause a large share of outages, and change-management discipline is the control most checklists leave out.
Build the checklist around four control families
1. Configuration backup and versioning
- Back up router, switch, firewall, and wireless controller configurations on a fixed schedule and before every change.
- Store copies off the device, a versioned repository or secure file store, so a failed device can be replaced from a known-good config.
- Record the device model, firmware version, and date with each backup so restores match hardware.
2. Staged changes and rollback plans
- Make changes in a lab or pilot group first when the change touches routing, firewall policy, or authentication.
- Write a rollback plan before the change window: the exact commands or steps to revert, who executes them, and how you will confirm the revert worked.
- Require a second reviewer for changes to core routing, VPN, and identity services.
3. Change windows and communication
- Schedule disruptive changes in defined low-traffic windows and notify affected users in advance.
- Freeze changes during peak business periods and around major releases.
- Log every change with what changed, why, who approved it, and the outcome.
4. Verification after change
- After each change, confirm connectivity, DNS resolution, VPN access, and monitoring alerts are healthy before closing the window.
- Compare monitoring baselines before and after to catch silent degradation.
Maintenance cadence that includes change control
Monthly
- Verify configuration backups completed and spot-check one restore to a spare device
- Review network logs and monitoring alerts for unusual activity
- Confirm firmware versions against the vendor’s current release and security advisories
- Test remote access and VPN connectivity
Quarterly
- Run full system backups and test recovery procedures
- Review and update network documentation and diagrams
- Test failover systems and disaster recovery plans (see the redundancy section)
- Audit user access permissions and remove inactive accounts
- Inspect physical infrastructure, cables, connections, cooling
Annually
- Perform a comprehensive security audit
- Update disaster recovery plans based on business changes
- Replace aging equipment before failure rates spike
- Review capacity planning against growth
- Train staff on incident response and change procedures
Treat the change log as a maintenance artifact. When an outage occurs, the first question is usually “what changed recently?” A clean change log answers it in minutes instead of hours.
Equipment quality still matters, cheap routers fail more often, but quality hardware cannot compensate for uncontrolled changes. Documentation is the most-skipped and most critical maintenance task: when you know what is connected where and what changed last, troubleshooting becomes systematic instead of guesswork.
Develop a Business Internet Outage Plan
Your outage plan should cover three phases: detection, response, and recovery.
Detection phase, How do you know there’s an outage? Who gets notified first?
Response phase, Who leads the incident response? What’s the communication protocol?
Recovery phase, How do you restore service? What gets restored first? How do you verify everything’s working?
Communication during an outage determines customer impact more than the outage itself.
Protect Your Infrastructure with Backup Power and Data Security
Power failures take down networks instantly. Backup power keeps infrastructure running, buying time for proper shutdown or failover.
Generators provide sustained backup power: a UPS covers minutes, a generator hours or days.
Battery backup for network equipment is non-negotiable. Routers, switches, and security appliances need power to function.
An effective backup strategy requires three elements: multiple copies, offsite storage, and regular testing. One copy isn’t enough, onsite backups are vulnerable to physical disasters, and untested backups might not restore correctly when you need them.
The National Institute of Standards and Technology (NIST) cybersecurity framework recommends regular backup testing as a core security practice.
Encryption protects data both in transit and at rest. Network traffic should be encrypted so intercepted data remains unreadable.
Get Started with Proactive Network Management Today
Every minute of network downtime drains productivity and erodes customer trust. Prevention is always cheaper than recovery.
This isn’t complex, but it requires commitment. Starting small with one or two improvements beats doing nothing.
According to the Uptime Institute’s 2026 infrastructure survey, organizations with documented disaster recovery plans and regular testing experience 70% fewer unexpected outages than those without formal plans.
At A PC Geek, we help businesses implement these exact strategies. Our proactive network management approach includes continuous monitoring, redundancy planning, maintenance scheduling, and disaster recovery testing. You can explore our network security services to see how we help prevent downtime before it happens, or learn more about managed IT support that handles redundancy and failover setup so your team can focus on core business operations.
The Federal Communications Commission (FCC) business continuity guidance emphasizes that network resilience requires both technical safeguards and organizational planning, exactly what we build for our clients.
The cost of prevention is measurable and manageable. Start with exploring cybersecurity solutions that protect your infrastructure, then discover how co-managed IT services can support your proactive management strategy.
Frequently Asked Questions
What are the most common causes of network downtime?
Network downtime stems from hardware failures, software bugs, security breaches, power outages, and configuration errors. Human mistakes during updates, lack of preventive maintenance, and inadequate redundancy are equally critical. In 2026, cybersecurity incidents have become a leading cause. Identifying which causes affect your business most helps you prioritize prevention efforts and allocate resources effectively.
How can network monitoring tools help prevent downtime?
Network monitoring tools track system performance continuously and send automated alerts when problems emerge. Early detection means your IT team can fix issues before they cascade into full outages. These tools measure mean time to detect and mean time to repair, giving you visibility into your network’s health. Continuous monitoring also helps you spot capacity constraints before they impact service availability.
What is the difference between network redundancy and failover?
Network redundancy means having backup systems in place, such as a secondary ISP, duplicate servers, or cellular backup connections. Failover is the automatic process that switches to those backups when the primary system fails. Together, they ensure business continuity by eliminating single points of failure. Testing your failover regularly ensures it works when you need it most.
How do I prepare my business for an internet outage?
Create a business internet outage plan that documents recovery procedures, assigns roles to staff, and lists critical systems that must stay online. Include contact information for your ISP and IT support, backup connectivity options, and communication protocols for notifying customers. Practice your disaster recovery plan annually so your team knows exactly what to do when an outage occurs, minimizing response time and business impact.
| Prevention Strategy | Implementation Timeline | Primary Benefit |
|---|---|---|
| Network monitoring tools | 1-2 weeks | Early problem detection |
| Redundant connections | 2-4 weeks | Automatic failover capability |
| Maintenance schedule | 1 week | Reduced equipment failures |
| Backup power systems | 2-3 weeks | Power outage protection |
| Data backups and testing | Ongoing | Data recovery capability |
| Outage response plan | 1 week | Organized crisis response |
